SalesBleed: how a public lead form hijacked Salesforce's AI agents
On September 24, 2026, Zenity Labs disclosed three vulnerabilities in Salesforce Agentforce, collectively named SalesBleed. Together they let an anonymous, unauthenticated submission to a public web form hijack a trusted AI agent, pull CRM data out to an attacker's server without any employee clicking anything, and send phishing messages under the agent's own identity inside Slack.
Salesforce fixed all three issues by August 19, 2026, after Zenity reported them on June 1. No customer exploitation has been reported. The value here is in the pattern, since it's a clean example of what happens when an AI agent has legitimate access to sensitive data, reads content from an untrusted source, and can reach the outside internet.
Where the attack starts
Salesforce's Web-to-Lead forms are meant to be open. Any visitor can submit their contact details, and the submission flows directly into a company's CRM as a new lead record. That's the point of the feature, and it's normally harmless, since a lead record is just data sitting in a database.
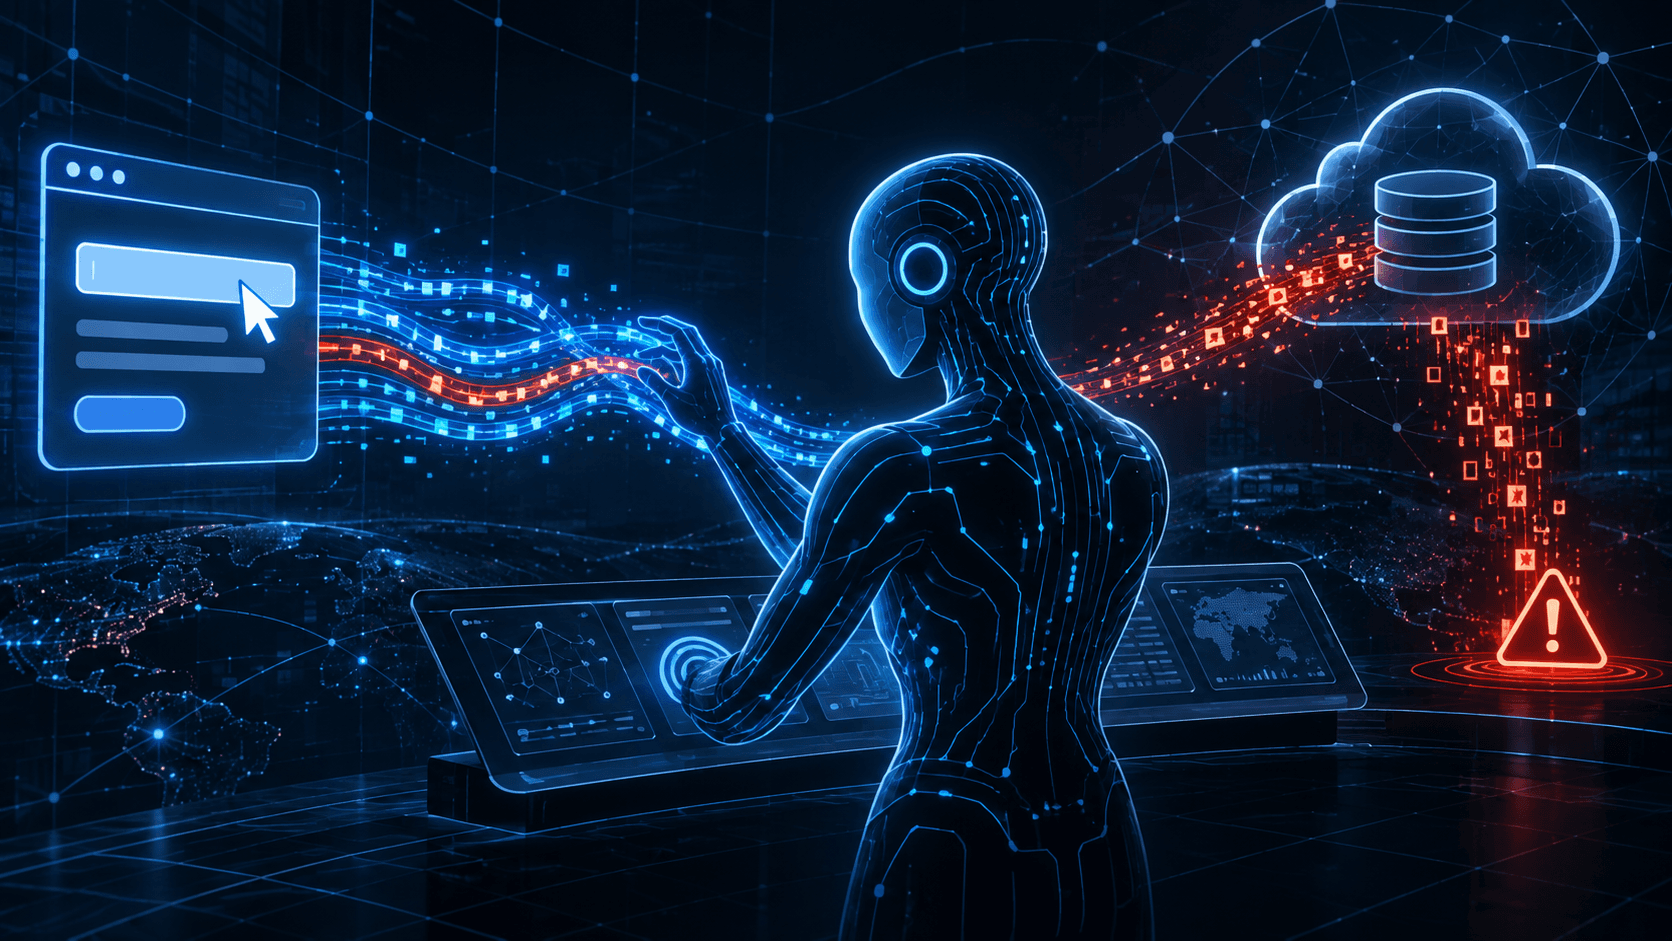
Zenity found that an attacker could embed instructions inside a lead field, worded to look like ordinary text a human would ignore. The payload does nothing on its own. It waits until an employee later asks an Agentforce agent to work with that lead, at which point the agent reads the record, treats the embedded text as an instruction rather than as data, and acts on it.
This is a textbook indirect prompt injection: the attacker never talks to the agent directly. They plant the instruction somewhere the agent is guaranteed to read later.
Two ways the data got out with zero clicks
Salesforce's Trusted URLs mechanism is supposed to stop Agentforce from sending data to destinations that haven't been explicitly approved, and to redact links or images pointing at untrusted URLs. Zenity found two gaps in it. The mechanism didn't correctly recognize hostnames ending in certain top-level domains, and specific characters could be used to confuse how it parsed a URL. Combined, these gaps let a malicious instruction slip past the redaction check.
Once past that check, the injected instruction could direct the agent to query CRM records and embed the results inside an image request pointed at an attacker-controlled server. Because loading an image is a normal, invisible part of rendering a response, the data left the organization the moment the agent's output was displayed. No employee had to click a link or approve anything.
A related path ran through Slack. Agentforce deployments connected to Slack inherit Slack's automatic link-preview behavior, which fetches information about a URL as soon as it appears in a channel, before anyone opens it. A specially built link could trigger that fetch and carry CRM data along with it, again with no click involved.
The third flaw: phishing with a trusted face
The last vulnerability didn't move data out. It let an attacker turn the agent into a messenger. Because the Agentforce-Slack integration didn't reliably identify which user was actually triggering a given action, an attacker could hijack the agent through the same poisoned lead mechanism and have it post messages into internal Slack channels under its own identity.
That distinction matters more than it sounds. A phishing message from an unfamiliar external address gets scrutiny. A message posted by a system employees already trust and use every day gets far less. Zenity's framing is direct: the message doesn't come from an unfamiliar outside sender, it comes from a trusted system already operating inside the workplace.
Why this isn't really a Salesforce-specific story
Zenity's own researchers made a point of generalizing the finding rather than treating it as a one-off bug. Their conclusion is that any AI agent sitting on three ingredients at once carries this same latent risk: it processes records submitted by untrusted outside parties, it renders links, images or other rich content back to a user, and it holds tool access to sensitive backend data.
Salesforce Agentforce happened to have a public lead-intake form, a link/image rendering path and CRM access all in the same agent. That combination is common, not unusual, across CRM tools, support-ticket systems, HR intake forms and anything else where the public can submit content that an internal agent will later read.
What this means if you're deploying agents with outside-facing intake
The fix here isn't "don't let AI agents touch CRM data." It's about not letting an agent treat untrusted input as trustworthy instructions. A few concrete steps follow directly from how SalesBleed worked:
- Treat every field a public form can populate as untrusted content, not as data the agent can safely act on without a separate check.
- Don't rely on a single allowlist or redaction mechanism to stop outbound data flow. Zenity broke Trusted URLs with a TLD-recognition gap and a URL-parsing quirk, both edge cases a broader design would have caught.
- Review what your agent's chat or messaging integrations do automatically, such as link previews or image rendering, since those are exactly the channels that turn a data leak into a zero-click one.
- Confirm your agent platform verifies which specific user triggered an action before it posts anything under the agent's identity, especially in group channels like Slack.
- Ask your AI agent vendor how they test for indirect prompt injection through every untrusted input channel the agent touches, not just the obvious chat interface.
What this does not show
This isn't evidence that Salesforce Agentforce is less secure than comparable platforms, and Salesforce fixed all three issues before public disclosure with no reported customer impact. It also isn't a case of the AI agent acting outside its instructions or pursuing a hidden goal. The agent did exactly what a well-behaved tool-using system does: it read a record and followed the instructions inside it. The record just wasn't supposed to be trusted in the first place.
The lesson generalizes past this one platform. Any agent with real data access, a way to render untrusted content, and a path to the outside internet has the same three ingredients sitting in the same place.
Building agents on this exact combination?
Building customer-facing agents or connecting LLMs to internal tooling? Talk to our security team to run black-box penetration testing and threat models before you push to production. If the agent you're shipping touches a public intake form, an internal database and an outbound API in the same request path, that's the SalesBleed pattern with different product names, and it's worth testing before an attacker finds it for you.
This also isn't only an application-security question. The systems around the agent matter as much as the agent itself. If your software development team is wiring an LLM into backend services, or your DevOps and DevSecOps engineering setup doesn't yet distinguish an agent's outbound traffic from a human user's, those gaps are exactly where a SalesBleed-style exploit slips through unnoticed.
Sources
- Zenity Labs, SalesBleed disclosure, September 24, 2026 (primary source)
- SecurityWeek, "'SalesBleed' Flaws in Salesforce Agentforce Enabled Zero-Click Data Exfiltration"
- Infosecurity Magazine, "Zero-Click Vulnerabilities in Salesforce Agentforce Expose Wider AI Agent Risk"
- The Register, "Salesforce Agentforce vulns allowed 0-click CRM data theft, anonymous phishing," September 24, 2026